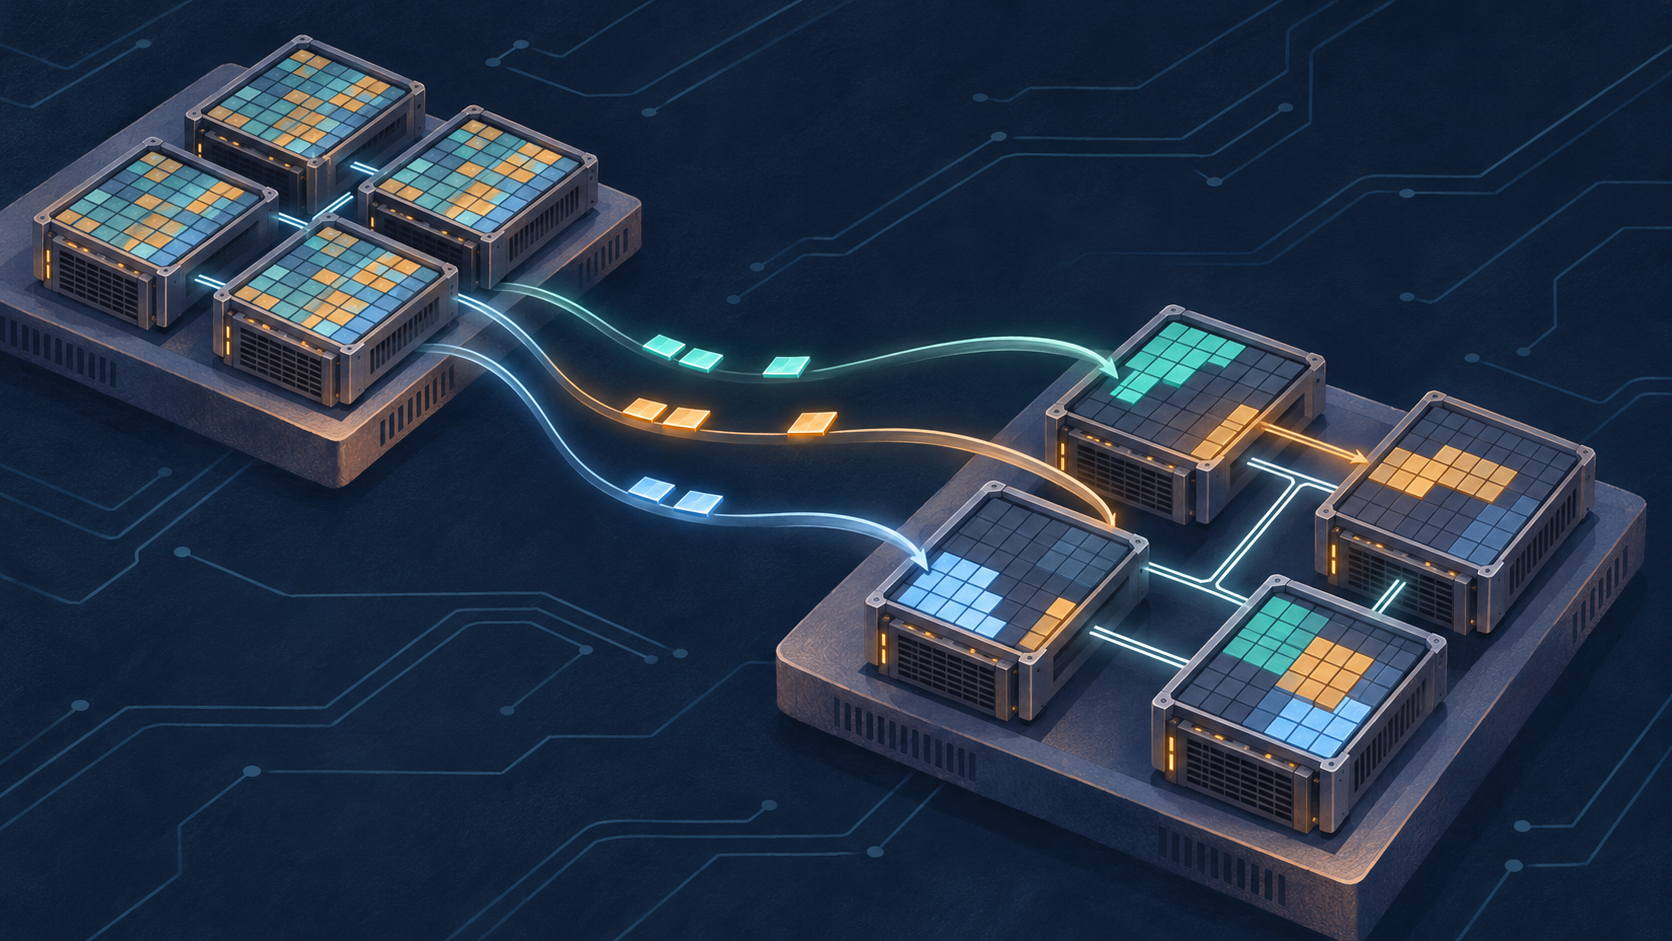
NVIDIA has reported lower latency for transferring updated model weights between training and inference GPUs during reinforcement learning post-training. In a company-authored technical article published November 6, 2026, it described four NeMo RL benchmark configurations in which a hybrid Reshard implementation delivered 2.7–5.7-fold speedups over conventional gather-and-broadcast transfers.
This transfer, called refit, keeps inference GPUs supplied with the latest policy weights while separate GPUs train the model. Training and inference can divide weights across GPUs differently. Conventional refit gathers parameter shards into complete tensors, broadcasts those tensors, and lets each destination retain its required portion. That can transmit data a destination does not need.
Reshard instead represents the source and destination layouts using PyTorch’s distributed tensor, or DTensor, abstraction. Its NCCL M2N implementation calculates the intersections between shards and transfers the required regions. It also groups destination replicas by NVLink domain, distributes incoming data among them, and uses local NVLink exchanges to assemble their weights while reducing duplicate network transfers. NVIDIA provides the reference implementation through its open-source nccl-extensions repository.
The measured NeMo RL implementation is hybrid: it uses Reshard for feed-forward projection weights, which NVIDIA says account for around 95% of parameters in the latest large language models, and retains gather-and-broadcast for other weights. This addresses practical differences in how engines partition different layer types.
On DGX H100, Qwen 3 235B refit latency fell from 6.4 to 1.9 seconds, approximately a 3.4-fold speedup. DeepSeek v3 671B fell from 14.9 to 2.6 seconds on H100, approximately 5.7-fold, and from 6.1 to 2.3 seconds on DGX GB200, approximately 2.7-fold. Nemotron Ultra v3 on GB200 fell from 8.2 to 2.3 seconds, approximately 3.6-fold. Each comparison used a specified combination of model, hardware and training-to-inference parallelism layouts.
A separate refit-only microbenchmark reported 4.3 seconds for Qwen3.8 2.4T with BF16 weights. The article did not supply a comparator latency, hardware platform or parallelism layout for that result. Its roughly 10 TB examples for conventional refit are logical payload estimates based on BF16 weights and two communication stages, rather than measured network traffic.
The findings support faster refit in the tested configurations, but do not establish equivalent gains in total RL training time or model quality. Only four comparative configurations were presented, and broader performance across hardware, layouts and precision modes remains unestablished. Timing repetitions, variability, confidence intervals, warm-up procedures, software versions and detailed network settings were not reported. The supplied source contains no independent replication and does not establish peer review. The reported gains apply to the hybrid implementation, not to Reshard operating on every parameter.
Source: NVIDIA Developer, November 6, 2026. https://developer.nvidia.com/blog/accelerating-reinforcement-learning-weight-refit-with-the-reshard-collective
Cover illustration generated with AI; conceptual, not research evidence.